Tech
From Data to Decisions: An End-to-End Data Engineering Success Story
 9 min read
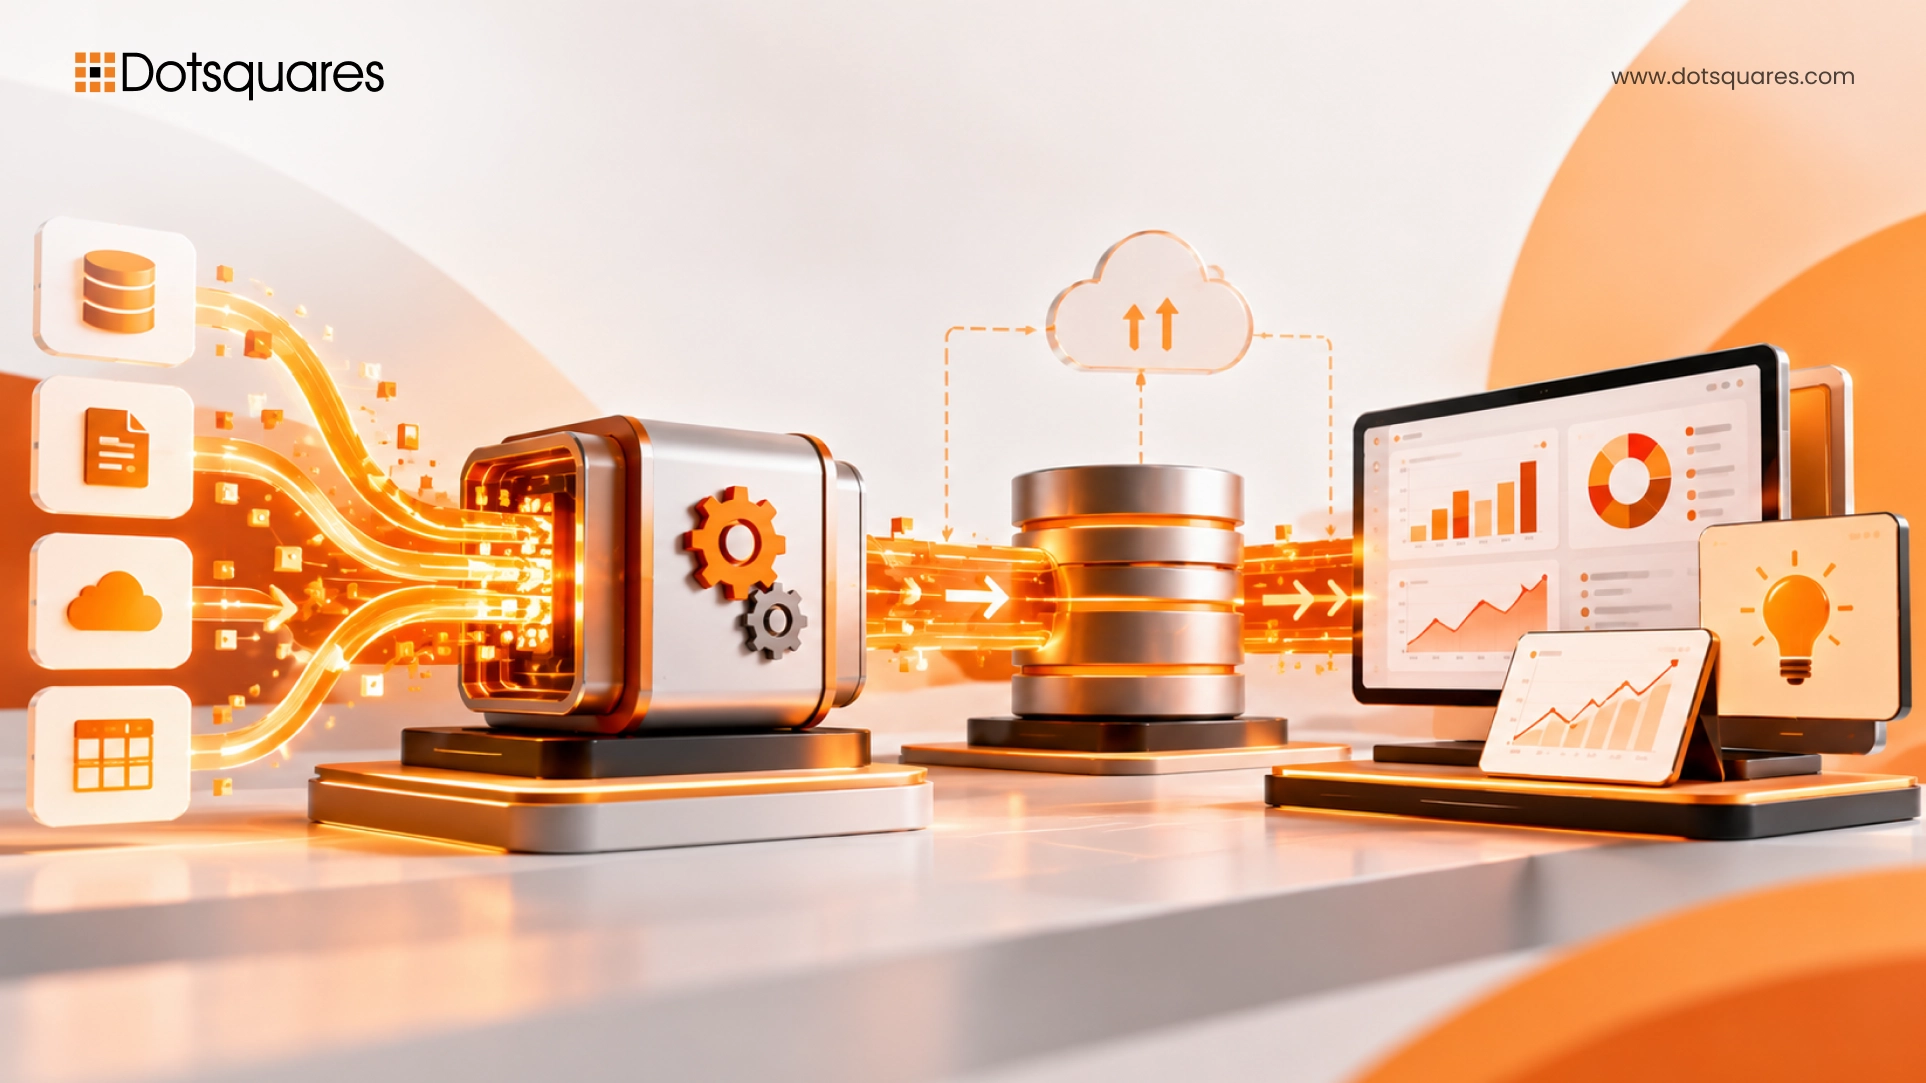
Most growing online businesses reach the same point. The database that runs the website is also the database answering every report. It works until the day it doesn't work.
At Dotsquares, we recently delivered an end-to-end data engineering project for a UK-based travel booking platform. We designed and built layer to layer by Dotsquares: ingestion from two very different source systems, a governed Lakehouse, automated Early Morning pipelines, and a Power BI report built from scratch to measure features like search-to-booking conversion and more.
This article walks through the problem, the architecture, the engineering decisions that mattered, and where the business stands now. If you are weighing up Microsoft Fabric, or your reporting still runs against your production systems, I hope it is useful.
The problem: two sources, no history, and a production database to protect
The client runs a high-traffic booking website backed by a production database on AWS. They needed to understand one thing above all: how many of the people who search for a journey actually go on to book it.
Answering that was harder than it sounds, for four reasons.
Production had to stay off-limits. Booking and journey data lived in the live MySQL/MariaDB database that serves customers. Any reporting query run directly against it would compete with the website for resources, and risk slowing things down for real customers at the worst possible moment.
Search history was disappearing. Search activity was captured in a logging and monitoring platform that keeps data for only around 15 days. Without intervention there would never be enough history for trends, seasonality or year-on-year comparison.
Two very different systems had to agree. Bookings came from a relational database; searches came from a rate-limited logging API. To measure conversion, both had to be reconciled into one coherent model, with the same clients, the same routes and the same date logic.
It had to be secure and easy to hand over. Connecting a report directly to production typically means VPNs, database drivers and credentials living somewhere they shouldn't. That is fragile and a security concern.
The mandate was clear: put all reporting data behind Microsoft Fabric so that production is never touched by analytics, build durable history, automate everything on a daily schedule, and deliver a Power BI report the business could trust.
The approach: four stages, one team
We framed the work as four stages, each with one clear responsibility: source, clean and transform, orchestrate, and represent. Owning all four meant every decision upstream could be made with the final report in mind.

Both sources land in the Lakehouse, Power BI reads only from the Gold layer, and a nightly pipeline runs every stage. The sections below walk through each one.
Stage 1: Source, bringing in two very different systems
The first job was getting data into Fabric without ever pointing analytics at production again. The two sources needed completely different treatment.
The production database. Booking and journey data is lifted into Fabric through a Microsoft on-premises data gateway. The gateway makes outbound-only connections, so the database is never exposed publicly and no inbound firewall rules had to be opened. From that point on, every report reads from Fabric, not from the live system.
The search logs. Search activity comes from a logging platform's API, which is rate-limited and paginated rather than query-able like a database. We wrote a Python notebook in Fabric to pull it reliably. It uses cursor-based pagination, paces its requests to stay comfortably within the API's limits, and backs off automatically when the API returns a rate-limit response. The result is an ingestion step that finishes cleanly instead of failing halfway through a run.
Stage 2: Clean and transform, a governed medallion Lakehouse
All data lands in a Fabric Lakehouse organised as a medallion architecture, with each layer doing one clear job.
Bronze is the system of record. It holds the full raw events, append-only and de-duplicated. Because the logging platform purges data after around 15 days, Bronze became the only durable home for search history. Every early morning it grows, and for the first time the business can look back further than two weeks.
Gold is shaped for reporting. Gold holds clean, modelled tables built to exactly what the Power BI report needs: consistent dates, client keys and standardised routes.
The business logic between the two layers is written in Spark SQL. The most interesting piece was route standardisation. Routes typed into searches and bookings rarely match character for character, so the transformation trims and collapses whitespace, normalises unicode, and builds direction-agnostic route keys so that A to B and B to A are treated as the same route. Journey classification and client mapping follow the same principle: one definition, applied consistently to both sources.
Before anything went live, the Fabric output was put through a parity gate. It was validated row for row against the source, checking both set equality and per-column equality. Nobody had to take the new numbers on faith; they were proven correct before the report was built on top of them.
Stage 3: Orchestrate, automated, monitored and recoverable
A pipeline that needs someone to babysit it isn't really finished. This stage was about making the platform run itself, tell us how it went, and recover if something goes wrong.
Incremental loads that capture change. Each night only new and changed data is pulled, using a watermark combined with a Delta MERGE (upsert) keyed on stable IDs. That means edits and cancellations are captured correctly, not just new bookings. Records that leave the active set are soft-deleted rather than silently lost.
A daily schedule. Fabric Data Pipelines run the full chain on a timezone-aware daily schedule: ingest, merge, then rebuild the Gold layer.
Alerts on every run. Success and failure notifications go out by email and Microsoft Teams, so the team knows the outcome of every run without having to check.
Backup and disaster recovery. A weekly backup copies the system-of-record data into an isolated backup workspace. Alongside it sits disaster-recovery tooling and a restore runbook, so the whole environment can be rebuilt if it ever needs to be.
Retention by design. Data is kept on a rolling 18-month window, enough for year-on-year comparison with some margin, and older data is pruned automatically.
Stage 4: Represent, a Power BI report built from scratch
With trusted, modelled data in place, We designed and built the Power BI semantic model and report from the ground up, reading directly from Fabric.
The model follows best practice rather than just working. It is a clean star schema with a dedicated Date dimension (auto date/time switched off), every measure kept in its own measures table, descriptive naming throughout, technical keys hidden from report users, and explicit data types on every column. That discipline pays off later: the model is easy to extend, easy to audit, and easy for someone else to pick up.
The report itself brings bookings and searches together in one place, with search-to-booking conversion at its centre. Because both sources share the same route, client and date logic upstream, the business can slice conversion by route, client and period and trust that the two sides line up.
It is also clean to own. The report file needs no VPN, no database drivers and no embedded credentials. Secrets live server-side in Fabric, which makes the report safer and simple to hand over.
What made the difference: four engineering lessons
The architecture diagram tells you what was built. These are the decisions that made it reliable.
- Time zones will find you. The source data used UTC while the business thinks in UK local time. Left alone, that mismatch would have silently dropped around an hour of data at every switch between GMT and BST. Fixing the watermark logic to handle this explicitly meant no rows go missing twice a year. It's the kind of bug nobody notices until the numbers stop adding up.
- New rows are the easy part. Most incremental loads handle inserts well. The real test is edits and cancellations, which are frequent in travel bookings. Keying the Delta MERGE on stable IDs, with soft-deletes for records that leave the active set, means the Lakehouse reflects what actually happened rather than what was first recorded.
- Prove it before you show it. The row-for-row parity gate was a hard acceptance test, not a nice-to-have. When stakeholders ask whether a number is right, the answer is backed by evidence rather than confidence.
- Treat the source's limits as a design input. A rate-limited API and a database you are not allowed to burden are constraints, not obstacles. Designing for them from the start, with pacing, back-off and an outbound-only gateway, is what keeps the pipeline quiet and dependable night after night.
The outcome
The client now has an analytics platform that is separate from production, with history that keeps growing and a pipeline that runs and monitors itself every early morning.
In practical terms:
- Reporting is fully decoupled from the production database, so the website is never competing with report refreshes.
- There is a single, governed source of truth in Microsoft Fabric, with durable search history that simply did not exist before.
- The full chain of ingestion, transformation, validation and refresh is automated, with alerting, backup and disaster recovery built in.
- The business has a best-practice Power BI report that measures many useful conversion, built on numbers that were validated before go-live.
- Credentials stay server-side, and the report is straightforward to maintain and hand over.
And it was delivered end to end by one team: source, clean, orchestrate and represent.
Closing thoughts
The technology in this project matters, but the bigger lesson is about ownership. When one team owns the whole journey, from the source systems to the report on someone's screen, problems get solved where they start rather than patched where they show up. A time-zone bug is fixed in the load, not explained away in a dashboard footnote.
At Dotsquares, we help companies build data platforms like this end to end on Microsoft Fabric and Power BI. If your reporting still leans on your production systems, or your history disappears faster than you can analyse it, We would be glad to talk it through. Feel free to contact us.


Related Post
 November 05, 2026
From Data to Decisions: An End-to-End Data Engineering Success Story
Explore how Dotsquares built an end-to-end data engineering solution using Microsoft Fabric and Power BI to automate data pipelines and improve booking analytics.
Keep Reading November 05, 2026
Django vs Flask vs FastAPI: Which Python Framework Is Right for Your Project?
Compare Django, Flask and FastAPI to understand their features, use cases and differences, and choose the right Python framework for your project.
Keep Reading November 04, 2026
Smart Contract Automation for Businesses: Use Cases and Benefits
Explore smart contract automation for businesses, including its key use cases, benefits, cost savings, security advantages and challenges across different industries.
Keep Reading